There is a statistic called the z-score, which is used to describe how much a value deviates from the mean. The equation goes like this (value - mean)/sd.
This works well for a normal distribution and the z-score can be used to identify outliers, usually a rule of thumb is 3 to 4.
However, when there are quite a few outliers, the distribution is not normal anymore, especially the sd can be inflated a lot by them. In this case, the z-score might look normal (<4) for some of the outliers.
To deal with this problem, the idea of median absolute deviation (MAD) is introduced. This is how it works:
- get the median from the samples
- minus median from everyone and take the absolute value, this is basically their distances from the median
- get the median of step 2, and it is MAD
Why this is going to help? First of all, instead of minus the mean, it minus the median. Secondly, instead of square, averaging then square root, it uses the median of the distance, or the absolute value. This is the raw mad. Then using it we got something called the “robust z-score”.
Look at the three forms of z-score below:
- the concept of z-score: (value - center) / spread
- normal z-score: (value - mean) / sd
- robust z-score: (value - median) / mad
We already know that when the distribution is normal, median = mean. How about mad? Would mad = sd if the distribution is normal?
The answer is no! Oh my. Damn stats. OK let’s work out the relationship between mad and sd under a normal distribution.
Remember there was this magic number, 1.96, in normal distribution? sd * 1.96 would cover 95% of a normal distribution (two-tailed). Today we are going to introduce another magic number: 1.4826
If we check the function mad in R, it looks like this:
mad
function (x, center = median(x), constant = 1.4826, na.rm = FALSE,
    low = FALSE, high = FALSE)
{
    if (na.rm)
        x <- x[!is.na(x)]
    n <- length(x)
    constant * if ((low || high) && n%%2 == 0) {
        if (low && high)
            stop("'low' and 'high' cannot be both TRUE")
        n2 <- n%/%2 + as.integer(high)
        sort(abs(x - center), partial = n2)[n2]
    }
    else median(abs(x - center))
}
<bytecode: 0x63f7f80ff270>
<environment: namespace:stats>
This low/high part is telling the program what to do if the number of values are even. Mean by default, or you can ask it to use the lower or the higher one if you prefer to use one of the values. So this whole function can be boiled down to:
1.4826 * median(abs(x - median(x)))
So now, why 1.4826?
In order to use the MAD as a consistent estimator for the estimation of the standard deviation σ, a constant scale factor needs to be introduced, and its value depends on the distribution. So now we just need to calculate the MAD under a standardized normal distribution (mean = 0 and sd = 1), then we would know what the scale factor should be for it to be scaled back to 1.
The derivation process is demonstrated on the wiki page. It is pretty straightforward once you understand the following equation chain:
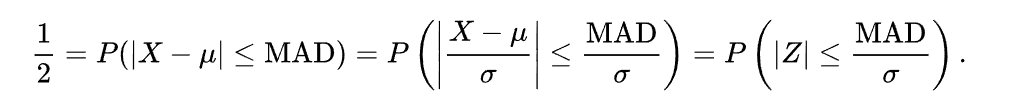
- in normal distribution, μ = median
- after step 2, where every value gets its distance from the median, MAD is the median distance. This means half of the values are even more dispersed (higher than MAD), and half of the values are tighter (lower than MAD), thus the 0.5.
- divide both sides by σ, and (x - μ) / σ is the standard normal variable which follows the z-distribution.
Once we understand the 0.5, then we will know the area under the curve between the two points is 0.5, which can be stated using the CDF (cumulative distribution function, or the pnorm() in R), that is, pnorm(MAD/σ) - pnorm(-MAD/σ) = 0.5.
Since the distribution is symmetrical, then we will have pnorm(-MAD/σ) = 1- pnorm(MAD/σ). Plugging this in will give us pnorm(MAD/σ) = 0.75. Then we can use the inverse of pnorm, which is qnorm, to calculate the ratio between MAD and σ. MAD/σ = qnorm(0.75) = 0.6745, σ = MAD/0.6745 = MAD * 1.4826. The magic number!
So by multiplying by 1.4826, the raw MAD rescales to sd for normal data, and we can use the same cutoff such as 3 or 4.
That stats seems to be the hardest word.